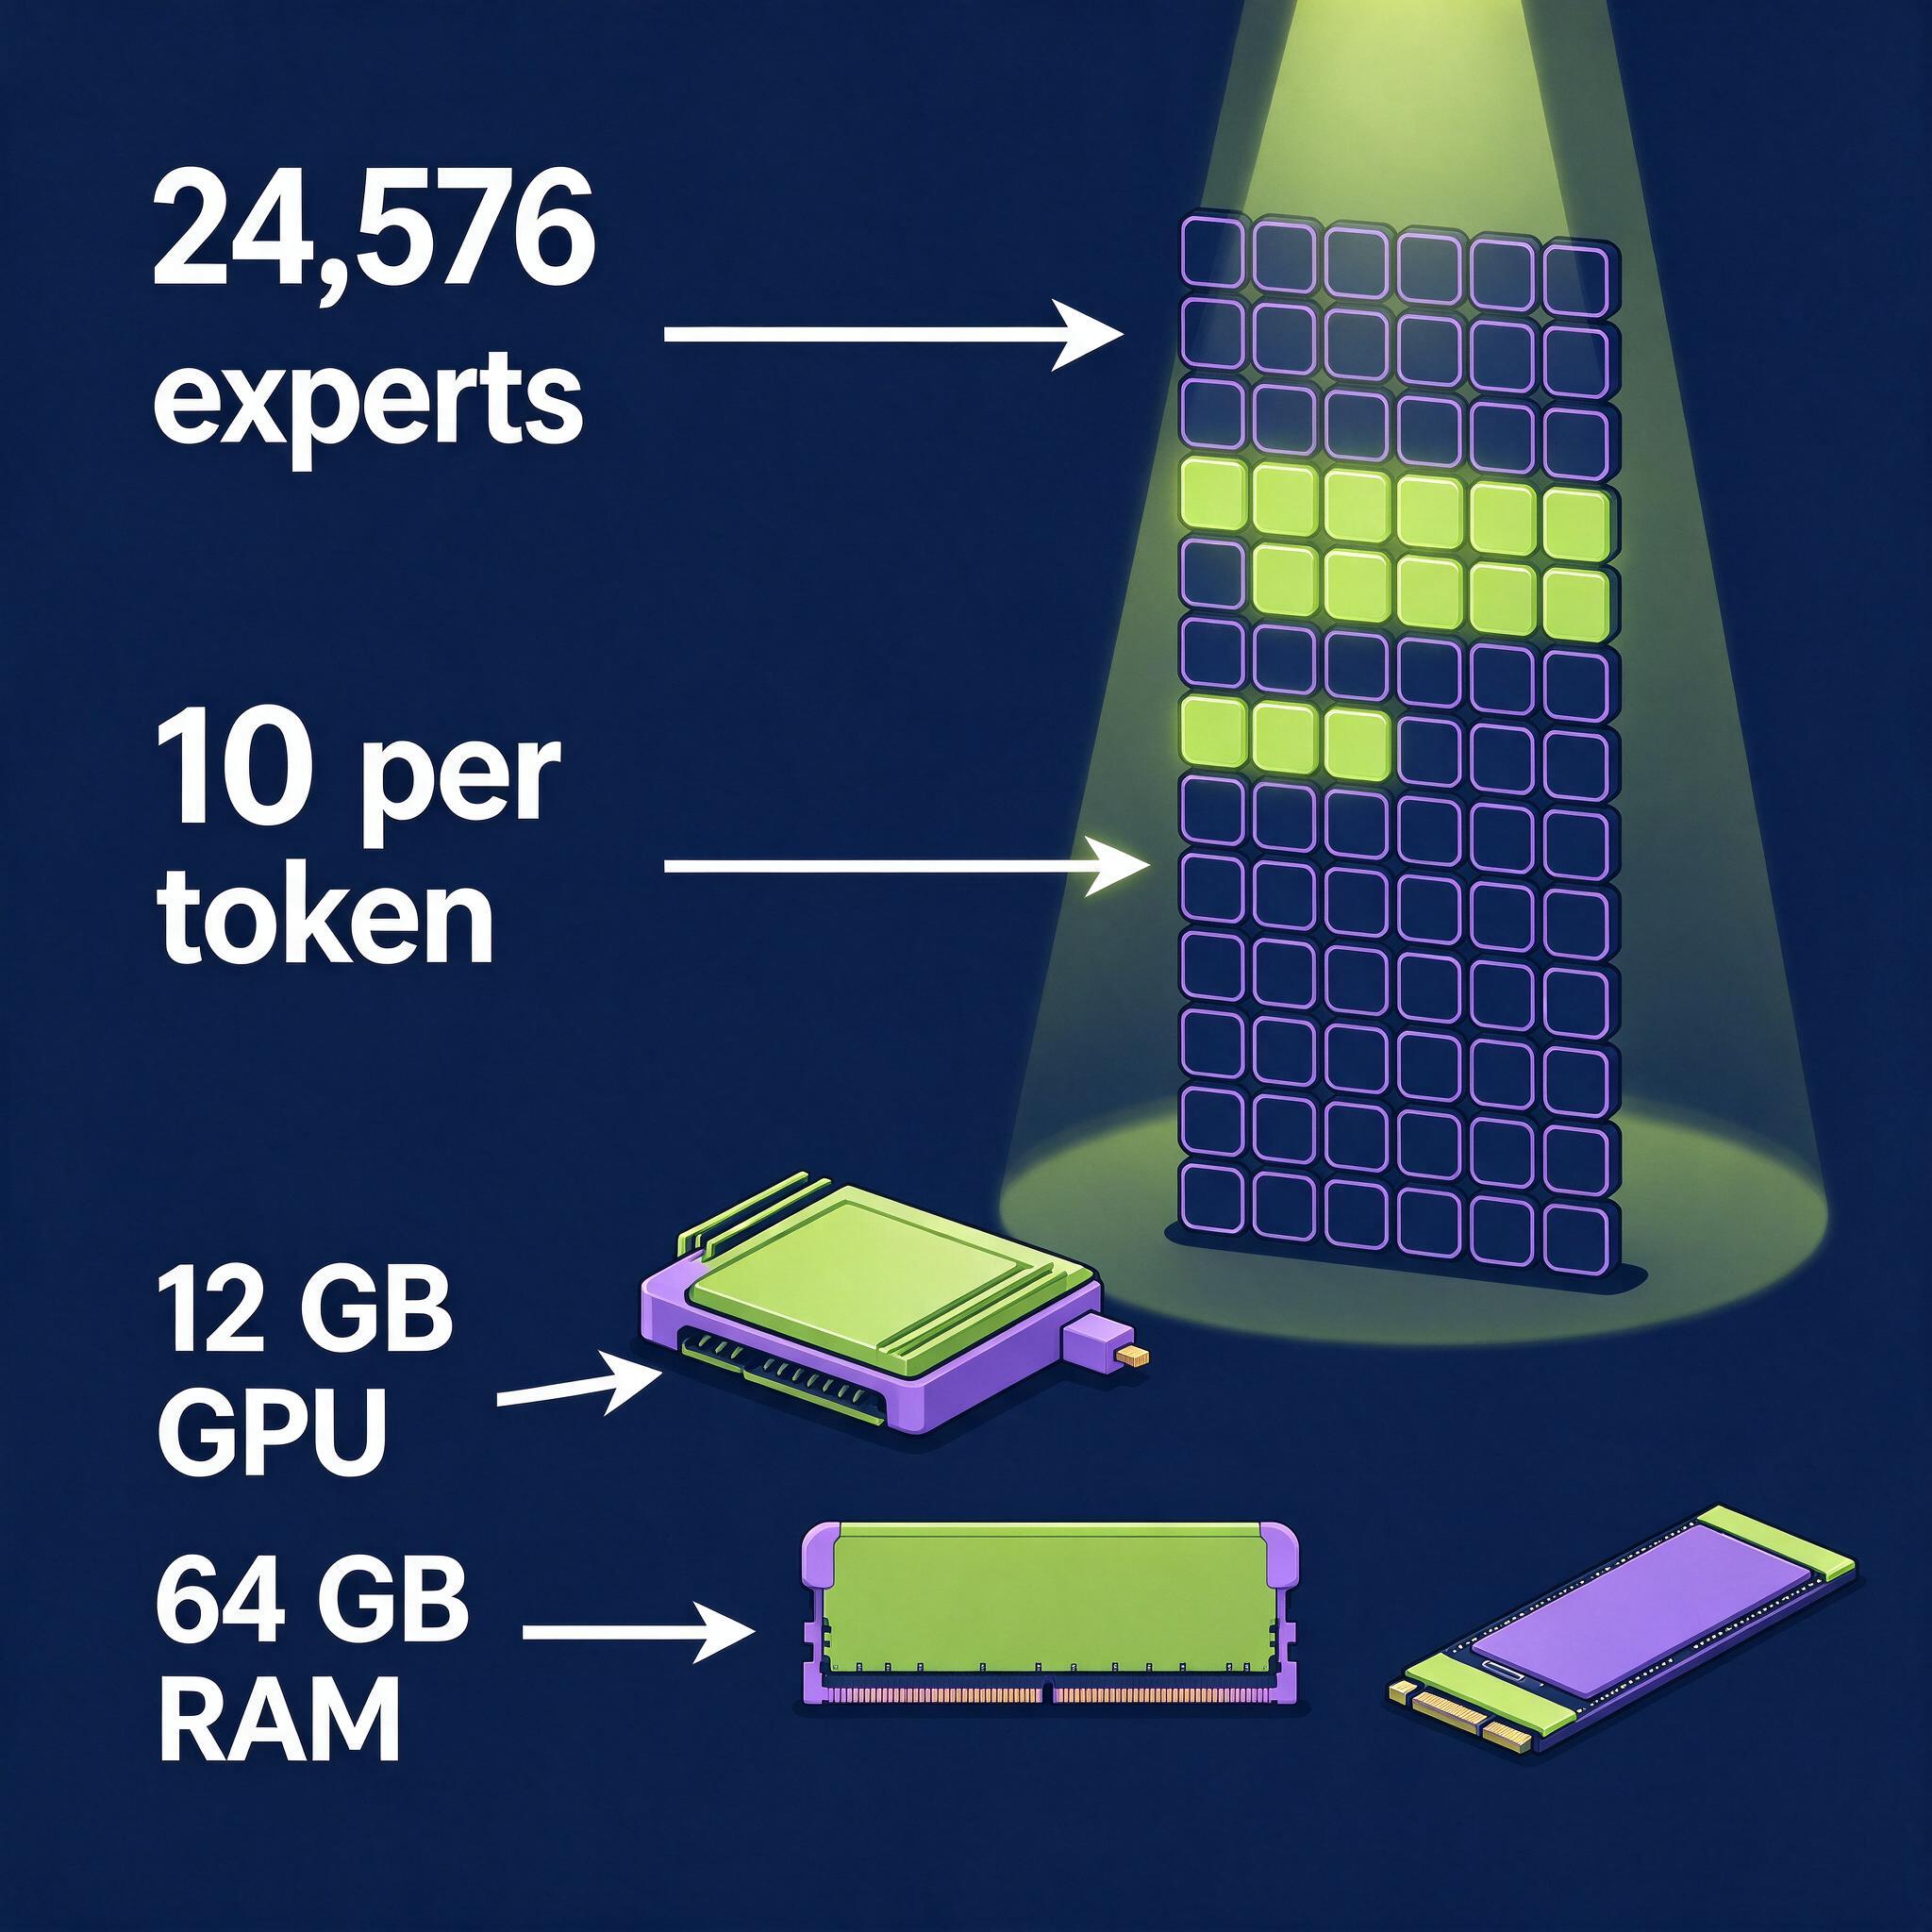
Strata serves a 125B MoE at 94 tokens/s from a 12 GB card and 64 GB of RAM
Strata runs Qwen3.8-Flash-Next by keeping all 24,576 experts in system RAM and computing the misses on the CPU while a 12 GB card works from a small adaptive expert cache. The project's measured tables show 93 to 94 tokens/s at a 4K context, 74 tokens/s with 128K tokens in the window, and 64 GB of RAM as the real requirement.